Here is a pattern that repeats across almost every organization trying to adopt AI automation: a team picks a promising use case, prototypes a workflow with an LLM, gets impressive demo results, and then spends months trying to make it work with the systems the business actually runs on. The model was never the bottleneck. The connections were.
The uncomfortable truth is that most AI projects are integration projects in disguise. The intelligence layer — the model, the prompt, the agent — is usually the smallest piece of the engineering work. The larger, harder, less glamorous work is getting clean data out of the systems that hold it, moving it reliably to where the AI needs it, and routing the AI's output back into the workflows people already use.
This is not a new problem. It is the same problem that has defined enterprise software for decades: how do you connect CRM and ERP systems, legacy databases, SaaS platforms, and internal tools into something that behaves like a single coherent system? AI just raises the stakes because the intelligence layer is only as good as the data it receives.
Why Automation Projects Fail Before the AI Even Runs
When an automation project stalls, the instinct is to blame the model. The outputs are inconsistent. The workflow produces hallucinated data. The agent makes decisions that do not match reality. But trace the root cause backward and you almost always land on one of three integration failures.
1. The Data Is Fragmented Across Systems That Do Not Talk to Each Other
A business might have customer data in a CRM, order data in an ERP, support tickets in a helpdesk tool, and product usage metrics in an analytics platform. Each system has its own schema, its own identifiers, its own update cadence. Building an AI workflow that needs a unified view of a customer means first solving the integration problem that existed long before anyone mentioned AI. Without a reliable data pipeline feeding clean, reconciled data to the model, the AI is working with an incomplete and often contradictory picture.
2. There Is No Reliable Way to Move Data In and Out
A prototype might pull data from a CSV export or a one-time API call. Production requires something different: scheduled syncs, event-driven triggers, error handling, retry logic, and monitoring. API integration for business automation is not just about making a single successful request. It is about building a pipeline that handles the inevitable failures — rate limits, schema changes, expired tokens, partial responses — without losing data or producing silent errors that corrupt downstream results.
3. The AI Output Has No Path Back Into the Business
An AI that generates a recommendation, a classification, or a drafted response is only useful if that output reaches the right person or system at the right time. If a sales team has to copy and paste AI-generated insights from one tool into their CRM, adoption will collapse within weeks. The output path matters as much as the input path, and designing it well requires understanding how people actually work inside the systems they already have.
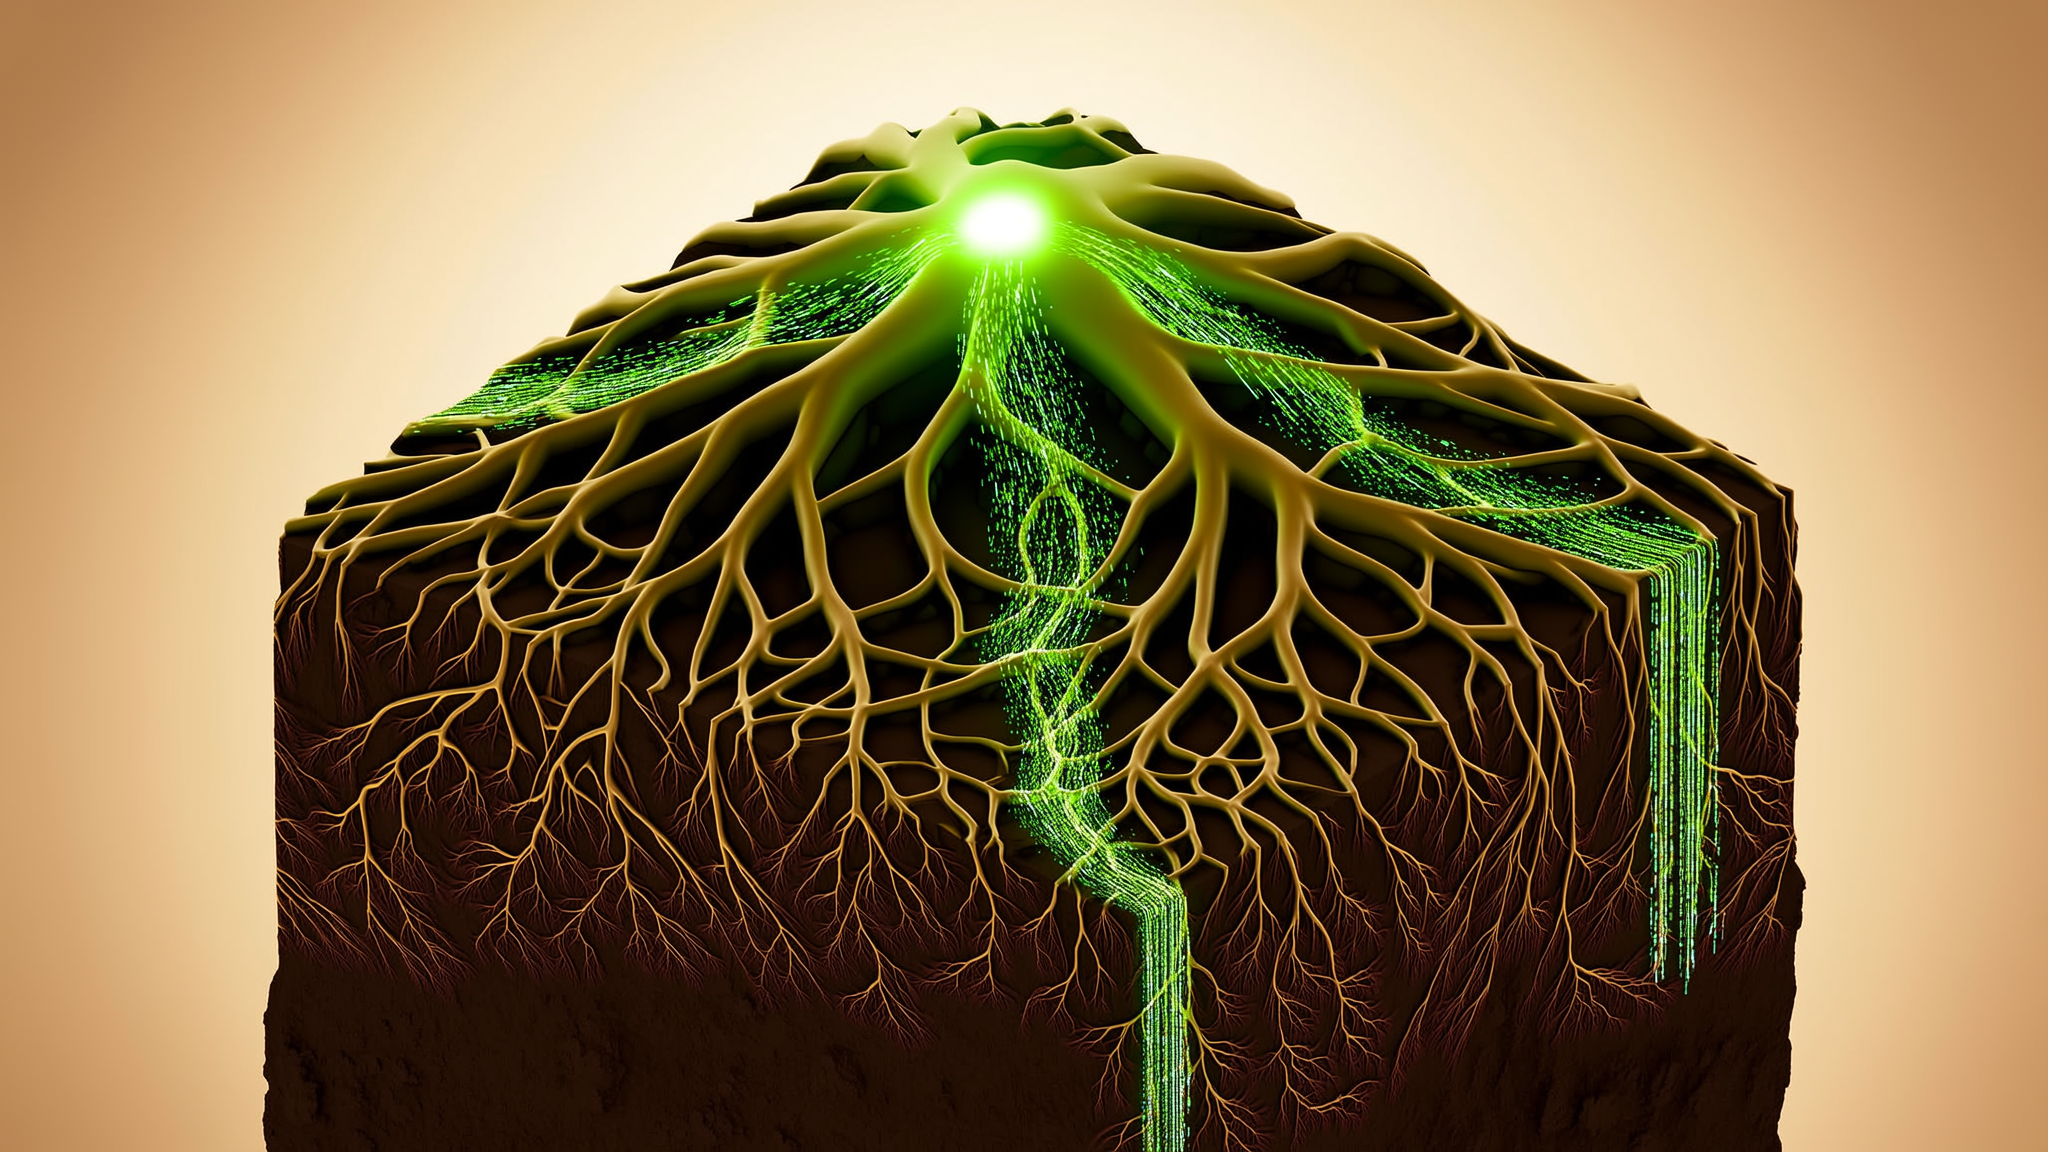
Integration Is the Soil Work — AI Is the Fruit
This framing is not meant to diminish the value of the AI layer. A well-designed prompt system, a retrieval-augmented generation pipeline grounded in accurate internal knowledge, or a multi-agent orchestration that coordinates complex multi-step tasks — these are genuinely powerful capabilities. But they grow from a foundation. And the foundation is integration.
Think of it in terms of layers:
- Layer 1: Systems and data. The CRM, ERP, databases, SaaS tools, and internal applications where business data lives. These are the source of truth.
- Layer 2: Integration and pipelines. The APIs, ETL processes, event buses, and data pipelines that move information between systems, reconcile it, and make it available in a clean, consistent format. This is the soil work.
- Layer 3: Intelligence. The LLMs, agents, RAG systems, and automation workflows that act on the data. This is where the visible value appears — but it is entirely dependent on the layers beneath it.
When organizations skip Layer 2 and jump straight to Layer 3, they build automation on a foundation that cannot support it. The result is brittle workflows that break when a field name changes in the CRM, when an API version is deprecated, or when a new data source needs to be incorporated.
What Durable Integration Actually Looks Like
Building integration that lasts — integration that can support AI today and whatever comes after AI tomorrow — requires a different set of priorities than building a demo. These are the principles that hold across industries and system landscapes.
Design for the Contract, Not the Implementation
Every connection between two systems should be governed by a clear contract: what data moves, in what format, how often, and what happens when something goes wrong. When you connect CRM and ERP systems through a well-defined API contract, you can change the underlying implementation of either system without breaking the connection. This is the difference between integration that survives a platform migration and integration that has to be rebuilt from scratch.
In practice, this means investing in API design before writing integration code. It means defining schemas explicitly rather than passing raw responses from one system to another. And it means versioning those contracts so that changes can be introduced without breaking existing consumers.
Build Observability Into the Pipeline, Not Around It
A data pipeline for AI is only trustworthy if you can see what is moving through it. This means logging not just errors but data quality metrics: record counts, null rates, schema validation results, latency measurements. When an AI workflow starts producing unexpected results, the first question should not be "what is wrong with the model?" but "what changed in the data?" — and observability in the pipeline should answer that question in minutes, not days.
This is a lesson from infrastructure engineering that applies directly to AI automation. The same rigor that goes into monitoring a production Kubernetes cluster — the same attention to alerting thresholds, dashboards, and incident response — belongs in the data pipelines that feed AI systems.
Automate the Connection, Not Just the Task
Most conversations about AI automation focus on automating a task: drafting an email, classifying a support ticket, generating a report. But the higher-leverage automation is often in the connections between tasks. Moving data from the system where it is created to the system where it is needed, transforming it along the way, validating it against business rules, and routing it to the right destination — this is workflow automation at the integration layer, and it compounds in value because every new AI capability you add benefits from the same clean data infrastructure.
Plan for the Human Step
Durable automation almost always includes a human approval or review step, especially in the early stages. Designing integration with that step in mind — making it easy for a person to see what the AI is about to do, approve or correct it, and have that feedback improve the system — is fundamentally different from designing a fully autonomous pipeline that you hope works correctly. The human step is not a weakness in the system. It is a design choice that builds trust and catches errors before they reach customers or partners.
At FigTree, we run our own content production on this principle. The automated pipelines that produce and distribute this blog include human review at defined checkpoints. The automation handles the repetitive work. A person handles the judgment.
The Expertise That Matters Is Not New
There is a tendency in the AI conversation to treat everything as unprecedented. New models, new capabilities, new paradigms. And at the intelligence layer, much of it genuinely is new. But at the integration layer — the layer where most projects succeed or fail — the expertise that matters is the same expertise that has been built over decades of connecting enterprise systems.
Understanding how to design APIs that handle failure gracefully. Knowing how to build ETL pipelines that reconcile data from systems with incompatible schemas. Recognizing when a direct point-to-point integration will create maintenance debt versus when an event-driven architecture will scale cleanly. These are not AI skills. They are integration skills, and they have been refined through 25 years of building software across healthcare, financial services, media, and SaaS — across systems that were never designed to work together but had to.
Our partner Stephen McDermott brings exactly this kind of foundational experience to FigTree's architecture work. Over 25 years of building service layers, API platforms, ETL systems, and data pipelines across complex enterprise environments, the pattern is always the same: the organizations that invest in clean, well-architected integration before layering on new capabilities are the ones whose systems hold up under real production load. The organizations that skip that work end up rebuilding under pressure.
A Practical Starting Point
If you are evaluating an AI automation initiative — or recovering from one that stalled — here is a grounded way to assess where you actually stand:
- Map your data sources. Where does the data your AI workflow needs actually live? How many systems hold pieces of it? How do those systems expose data — APIs, database queries, file exports, webhooks?
- Assess the gaps. Can you get a unified, accurate view of the entity your AI needs to reason about (a customer, an order, a case) from a single query? If the answer is no, you have an integration problem to solve before you have an AI problem to solve.
- Evaluate your pipeline maturity. Do you have automated, monitored data pipelines — or manual exports and one-off scripts? The reliability of your AI output is capped by the reliability of your data pipeline.
- Identify the highest-leverage connection. Not every integration needs to be built at once. Find the single connection — the one data flow from one system to another — that would unlock the most value for your automation goals. Start there. Build it with production rigor. Then expand.
This approach is less dramatic than launching a company-wide AI initiative. It is also far more likely to produce automation that is still running and delivering value a year from now.
Related service: AI automation and workflow services in Tampa Bay — what we build, how we work, and what it costs.
Start With the Roots
The most valuable thing a systems integration consultant can tell you about your AI project might have nothing to do with AI. It might be that your CRM and ERP data are reconciled by a person in a spreadsheet every Friday, and until that is automated and validated, no AI workflow built on top of it will be trustworthy.
That is not a disappointing answer. That is a clear answer. And clear answers are where real progress starts.
At FigTree Development, we start every engagement with a Discovery and Strategy process designed to find exactly these leverage points — the foundational integration work that makes everything built on top of it more reliable, more scalable, and more durable. We are not interested in selling an AI demo. We are interested in mapping the automation opportunities where the investment compounds, so you spend less time on repetition and more time on the work that actually grows your business.
If you are trying to figure out where integration gaps are limiting your automation ambitions — or where to start so the foundation is right from day one — book a free 20-minute discovery call and we will walk through it together.